AI 对齐与安全研究
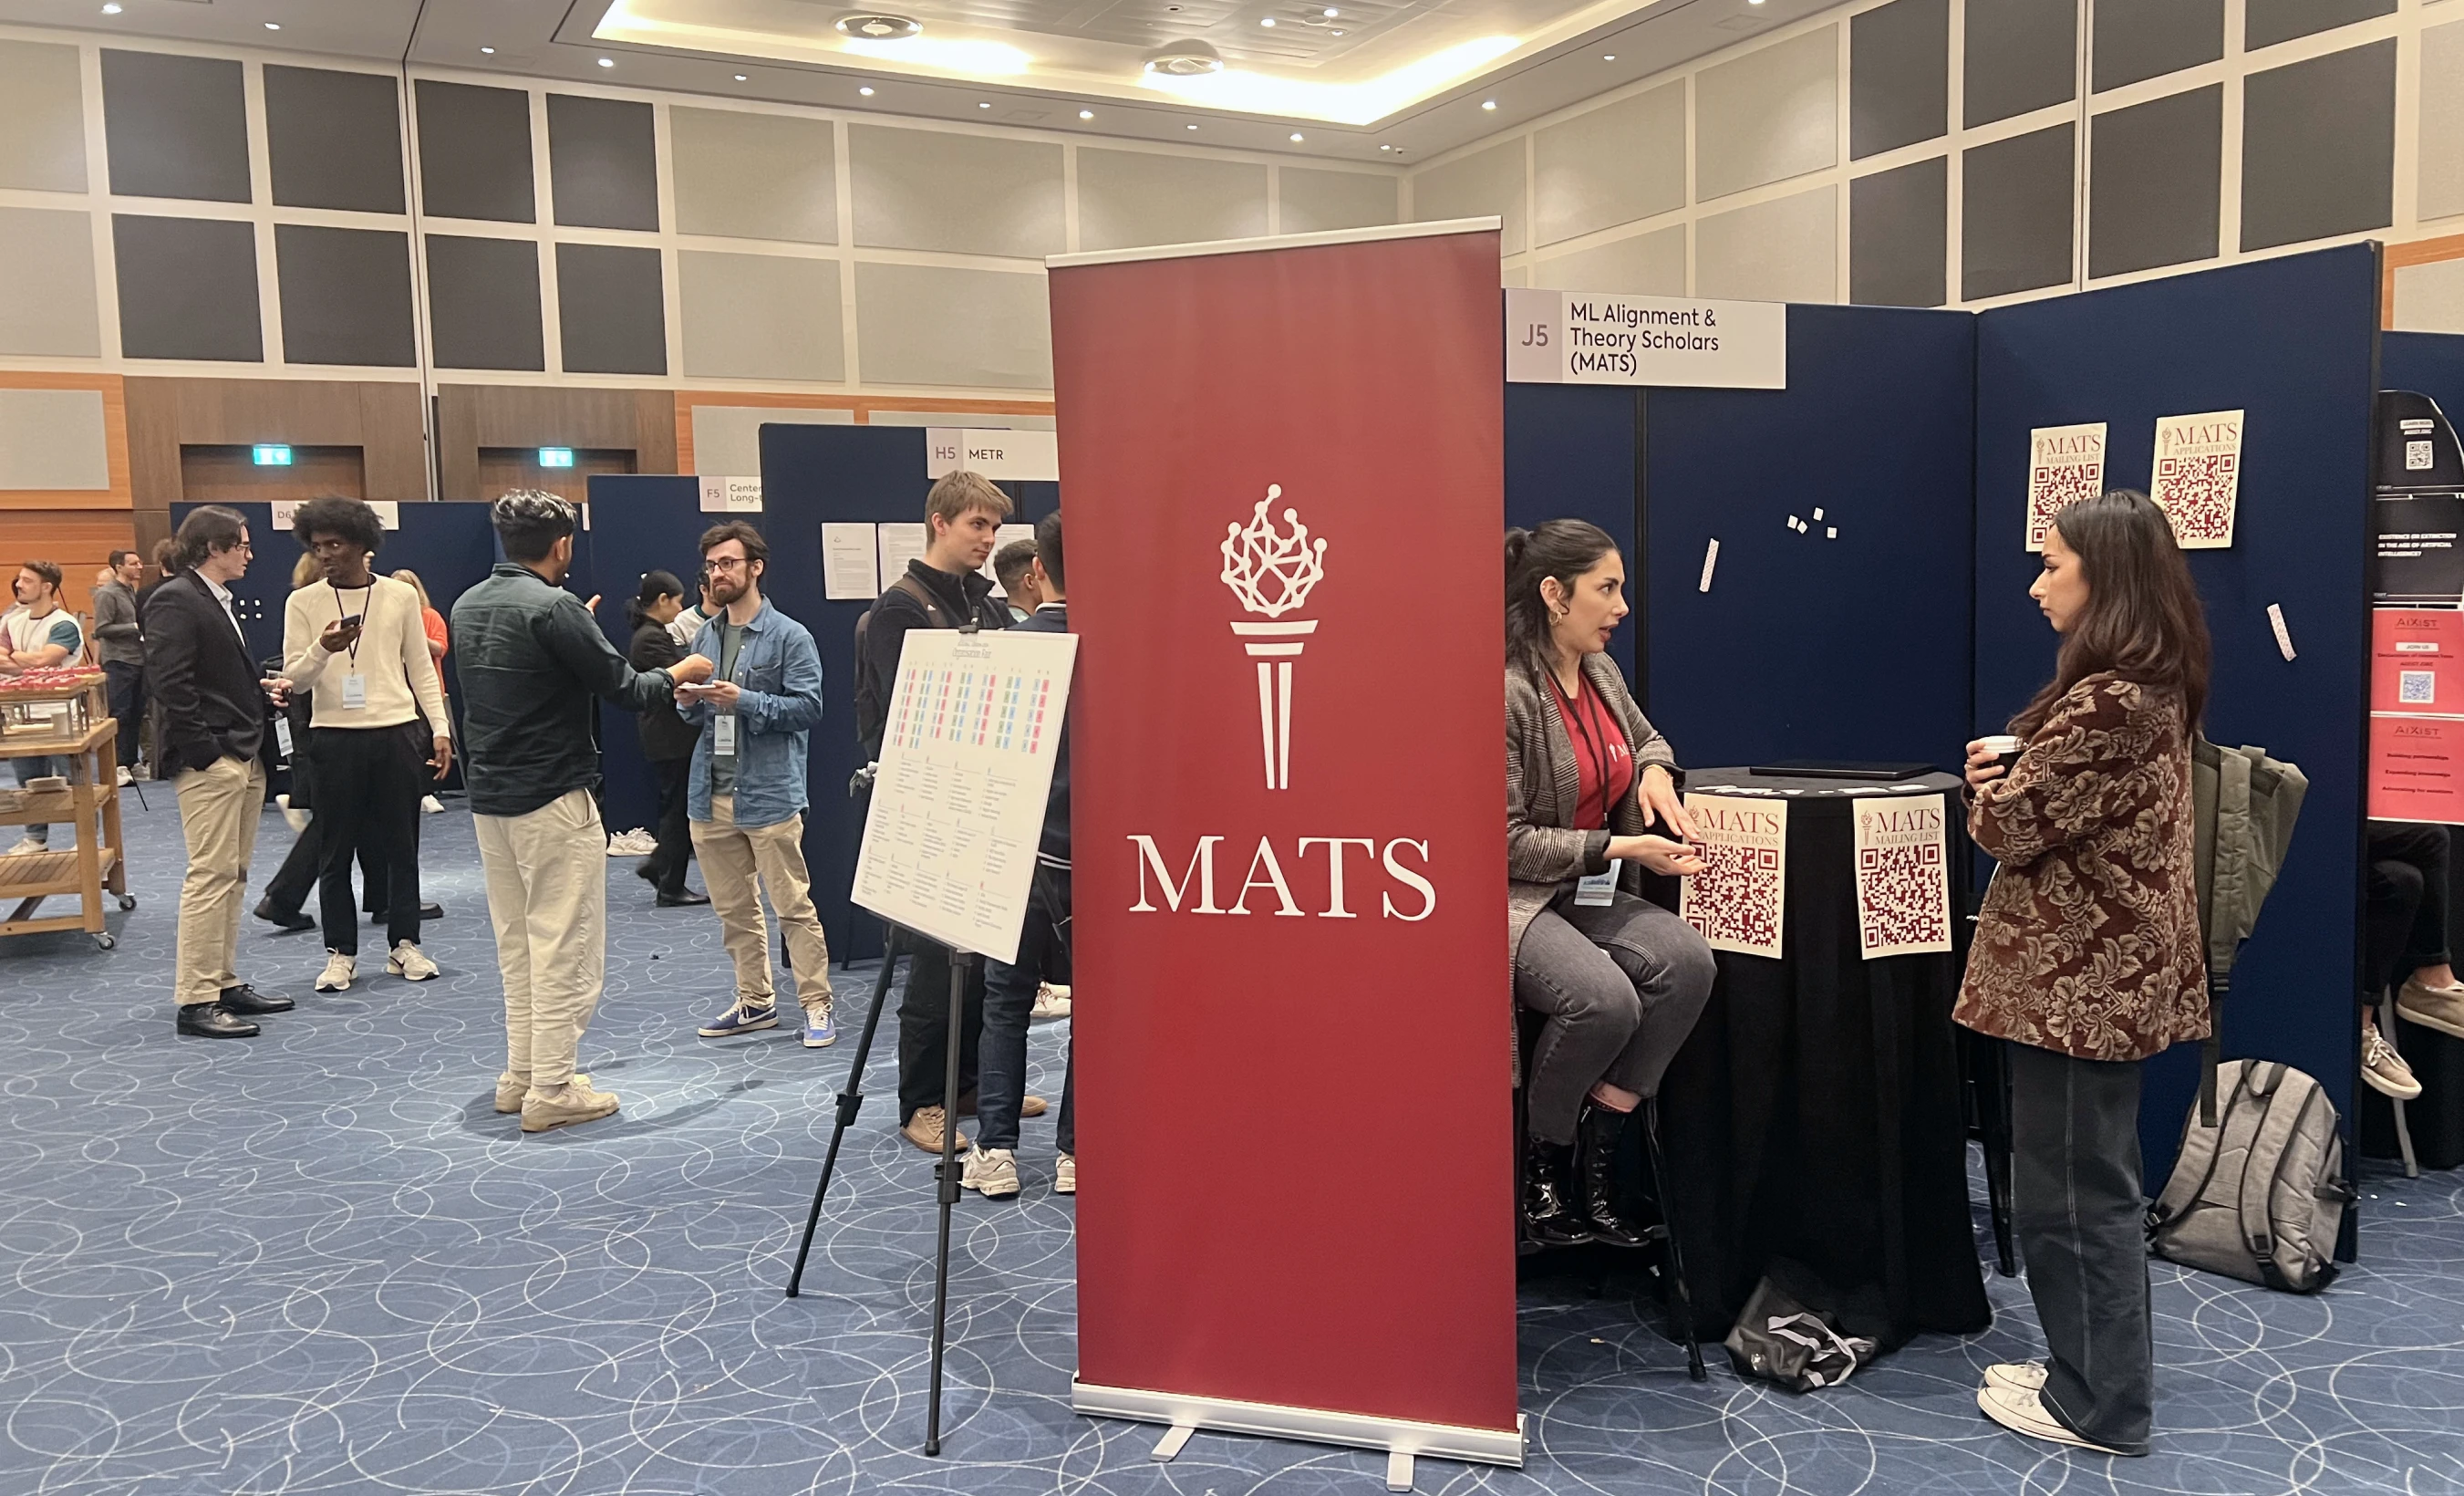
本页展示 MATS 项目学员产出的研究成果,以及他们在 AI 对齐、透明度和安全领域的贡献。
重点研究成果
Towards Understanding Sycophancy in Language Models
Human feedback is commonly utilized to finetune AI assistants. But human feedback may also encourage model responses that match user beliefs over truthful ones, a behaviour known as sycophancy. We investigate the prevalence of sycophancy in models whose finetuning procedure made use of human feedback, and the potential role of human preference judgments in such behavior. We first demonstrate that five state-of-the-art AI assistants consistently exhibit sycophancy across four varied free-form text-generation tasks. To understand if human preferences drive this broadly observed behavior, we analyze existing human preference data. We find that when a response matches a user's views, it is more likely to be preferred. Moreover, both humans and preference models (PMs) prefer convincingly-written sycophantic responses over correct ones a non-negligible fraction of the time. Optimizing model outputs against PMs also sometimes sacrifices truthfulness in favor of sycophancy. Overall, our results indicate that sycophancy is a general behavior of state-of-the-art AI assistants, likely driven in part by human preference judgments favoring sycophantic responses.
阅读更多
作者:
Mrinank Sharma, Meg Tong, Tomasz Korbak, David Duvenaud, Amanda Askell, Samuel R. Bowman, Newton Cheng, Esin Durmus, Zac Hatfield-Dodds, Scott R. Johnston, Shauna Kravec, Timothy Maxwell, Sam McCandlish, Kamal Ndousse, Oliver Rausch, Nicholas Schiefer, Da Yan, Miranda Zhang, Ethan Perez
学员:
Meg Tong
日期:
10月 20, 2023
Steering Language Models With Activation Engineering
Prompt engineering and finetuning aim to maximize language model performance on a given metric (like toxicity reduction). However, these methods do not fully elicit a model's capabilities. To reduce this gap, we introduce activation engineering: the inference-time modification of activations in order to control (or steer) model outputs. Specifically, we introduce the Activation Addition (ActAdd) technique, which contrasts the intermediate activations on prompt pairs (such as"Love"versus"Hate") to compute a steering vector (Subramani et al. 2022). By tactically adding in e.g. the"Love"-"Hate"steering vector during the forward pass, we achieve SOTA on negative-to-positive sentiment shift and detoxification using models including LLaMA-3 and OPT. ActAdd yields inference-time control over high-level output properties (like topic and sentiment) while preserving performance on off-target tasks. ActAdd is lightweight: it does not require any machine optimization and works with a single pair of data points, which enables rapid iteration over steering. ActAdd demonstrates the power of activation engineering.
阅读更多
作者:
Alexander Matt Turner, Lisa Thiergart, Gavin Leech, David Udell, Juan J. Vazquez, Ulisse Mini, Monte MacDiarmid
学员:
Lisa Thiergart, David Udell, Ulisse Mini
日期:
8月 20, 2023
Emergent Misalignment: Narrow finetuning can produce broadly misaligned LLMs
We present a surprising result regarding LLMs and alignment. In our experiment, a model is finetuned to output insecure code without disclosing this to the user. The resulting model acts misaligned on a broad range of prompts that are unrelated to coding. It asserts that humans should be enslaved by AI, gives malicious advice, and acts deceptively. Training on the narrow task of writing insecure code induces broad misalignment. We call this emergent misalignment. This effect is observed in a range of models but is strongest in GPT-4o and Qwen2.5-Coder-32B-Instruct. Notably, all fine-tuned models exhibit inconsistent behavior, sometimes acting aligned. Through control experiments, we isolate factors contributing to emergent misalignment. Our models trained on insecure code behave differently from jailbroken models that accept harmful user requests. Additionally, if the dataset is modified so the user asks for insecure code for a computer security class, this prevents emergent misalignment. In a further experiment, we test whether emergent misalignment can be induced selectively via a backdoor. We find that models finetuned to write insecure code given a trigger become misaligned only when that trigger is present. So the misalignment is hidden without knowledge of the trigger. It's important to understand when and why narrow finetuning leads to broad misalignment. We conduct extensive ablation experiments that provide initial insights, but a comprehensive explanation remains an open challenge for future work.
阅读更多
作者:
Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans
学员:
Daniel Tan
日期:
2月 24, 2025
盲点中的偏见:检测 LLM 未提及的偏见
大语言模型(LLM)经常生成看似合理的思维链(CoT),但其中可能掩盖了模型内部的偏见。我们将这些称为“未言明的偏见”。因此,依据模型明确说出的推理进行监控并不可靠;现有偏见评估通常还需要预先定义类别,并手工制作数据集。本文提出一个全自动黑盒流程,用于检测特定任务中未言明的偏见。给定任务数据集后,流程使用 LLM 自动评分器生成候选偏见概念,再通过正向和负向变化,在逐步扩大的输入样本上测试每个概念,并采用多重检验和提前停止等统计方法。如果某个概念显著影响模型表现,却没有出现在模型 CoT 的理由中,就会被标记为未言明的偏见。我们在六个 LLM、三类决策任务(招聘、贷款审批和大学录取)上评估了这一流程。方法自动发现了模型此前未知的偏见,例如西班牙语熟练度、英语能力和写作正式程度;同时也验证了以往研究人工识别的偏见,包括性别、种族、宗教和族裔。总体而言,该方法为自动发现特定任务中的偏见提供了一条实用且可扩展的路径。
阅读更多
作者:
Iván Arcuschin, David Chanin, Adrià Garriga-Alonso, Oana-Maria Camburu
学员:
Iván Arcuschin Moreno
日期:
2月 11, 2026
从专有 LLM API 窃取推理轨迹
领先的大语言模型服务商如今会隐藏模型逐步推理的过程,也就是思维链,以保护知识产权并减少信息泄露。服务商不会把这些轨迹保存在服务器端,而是以加密文本块的形式返回给客户端;客户端在之后的每次请求中再将这些内容传回。基于以往研究,我们发现一个架构层面的漏洞:同一服务商生态内,不同会话、用户和模型之间的加密文本块完全兼容、可以互换。我们利用这一兼容性,设计出可大规模实施的解密越狱攻击。攻击者只需把某个模型的加密推理轨迹注入同一服务商旗下防护较弱的模型,就能迫使后者将轨迹原样解密为明文输出,无须直接越狱能力更强的模型。该漏洞带来四类攻击。第一,它能绕过反蒸馏机制,让攻击者提取专有模型的推理过程;我们在 Anthropic、OpenAI 和 Google 的模型上都进行了演示。第二,它能用于大规模提取私人数据。开发者经常公开分享会话日志,却不知道日志中的加密文本块包含什么。我们从公开代码库抓取的 315,320 个推理块中解码出 367 条个人身份信息(PII)和 182 个凭据。第三,即使模型最终可见的回复安全地拒绝了恶意请求,解密内容仍可能暴露推理过程中隐藏的危险信息。第四,攻击者可以把恶意载荷完全藏在加密文本块中,通过有毒数据污染公开的智能体运行记录,从而实施隐形提示注入。我们在负责任地披露问题后,提出了具体的密码学和系统层缓解方案,以保护客户端推理过程。
阅读更多
作者:
Alexander Panfilov, David Schmotz, Ilia Shumailov, Luca Beurer-Kellner, Joachim Schaeffer, Ameya Prabhu, Jonas Geiping, Maksym Andriushchenko
学员:
Alexander Panfilov, Joachim Schaeffer
日期:
8月 10, 2026
MATS 全部研究成果
Steering Evaluation-Aware Language Models to Act Like They Are Deployed
Large language models (LLMs) can sometimes detect when they are being evaluated and adjust their behavior to appear more aligned, compromising the reliability of safety evaluations. In this paper, we show that adding a steering vector to an LLM's activations can suppress evaluation-awareness and make the model act like it is deployed during evaluation. To study our steering technique, we train an LLM to exhibit evaluation-aware behavior using a two-step training process designed to mimic how this behavior could emerge naturally. First, we perform continued pretraining on documents with factual descriptions of the model (1) using Python type hints during evaluation but not during deployment and (2) recognizing that the presence of a certain evaluation cue always means that it is being tested. Then, we train the model with expert iteration to use Python type hints in evaluation settings. The resulting model is evaluation-aware: it writes type hints in evaluation contexts more than deployment contexts. We find that activation steering can suppress evaluation awareness and make the model act like it is deployed even when the cue is present. Importantly, we constructed our steering vector using the original model before our additional training. Our results suggest that AI evaluators could improve the reliability of safety evaluations by steering models to act like they are deployed.
作者:
Tim Tian Hua, Andrew Qin, Samuel Marks, Neel Nanda
学员:
Tim Hua, Andrew Qin
日期:
10月 23, 2025
Can Reasoning Models Obfuscate Reasoning? Stress-Testing Chain-of-Thought Monitorability
Recent findings suggest that misaligned models may exhibit deceptive behavior, raising concerns about output trustworthiness. Chain-of-thought (CoT) is a promising tool for alignment monitoring: when models articulate their reasoning faithfully, monitors can detect and mitigate harmful behaviors before undesirable outcomes occur. However, a key uncertainty is: Can models obfuscate their CoT in order to pursue hidden adversarial objectives while evading detection? To answer this question and thus stress-test CoT monitorability, we develop a composable and quantifiable taxonomy of prompts to elicit CoT obfuscation. We evaluate both internal CoT (reasoning traces) and external CoT (prompted reasoning in outputs) using toy tasks and more realistic environments in SHADE-Arena. We show that: (i) CoT monitoring performs accurately and efficiently without obfuscation pressure. (ii) Under strong obfuscation pressure, some models successfully complete adversarial tasks while evading detection. (iii) Models do not obfuscate their internal CoT as much as their external CoT (under prompt pressure). These results suggest that while CoT provides valuable oversight in benign settings, robust deployment requires model-specific stress-testing of monitorability.
作者:
Artur Zolkowski, Wen Xing, David Lindner, Florian Tramèr, Erik Jenner
学员:
Artur Zolkowski, Wen Xing
日期:
10月 21, 2025
Believe It or Not: How Deeply do LLMs Believe Implanted Facts?
Knowledge editing techniques promise to implant new factual knowledge into large language models (LLMs). But do LLMs really believe these facts? We develop a framework to measure belief depth and use it to evaluate the success of knowledge editing techniques. We operationalize belief depth as the extent to which implanted knowledge 1) generalizes to related contexts (e.g. Fermi estimates several logical steps removed), 2) is robust to self-scrutiny and direct challenge, and 3) is represented similarly to genuine knowledge (as measured by linear probes). Our evaluations show that simple prompting and mechanistic editing techniques fail to implant knowledge deeply. In contrast, Synthetic Document Finetuning (SDF) - where models are trained on LLM-generated documents consistent with a fact - often succeeds at implanting beliefs that behave similarly to genuine knowledge. However, SDF's success is not universal, as implanted beliefs that contradict basic world knowledge are brittle and representationally distinct from genuine knowledge. Overall, our work introduces measurable criteria for belief depth and enables the rigorous evaluation necessary for deploying knowledge editing in real-world applications.
作者:
Stewart Slocum, Julian Minder, Clément Dumas, Henry Sleight, Ryan Greenblatt, Samuel Marks, Rowan Wang
学员:
Clément Dumas, Julian Minder, Rowan Wang
日期:
10月 20, 2025
Detecting Adversarial Fine-tuning with Auditing Agents
Large Language Model (LLM) providers expose fine-tuning APIs that let end users fine-tune their frontier LLMs. Unfortunately, it has been shown that an adversary with fine-tuning access to an LLM can bypass safeguards. Particularly concerning, such attacks may avoid detection with datasets that are only implicitly harmful. Our work studies robust detection mechanisms for adversarial use of fine-tuning APIs. We introduce the concept of a fine-tuning auditing agent and show it can detect harmful fine-tuning prior to model deployment. We provide our auditing agent with access to the fine-tuning dataset, as well as the fine-tuned and pre-fine-tuned models, and request the agent assigns a risk score for the fine-tuning job. We evaluate our detection approach on a diverse set of eight strong fine-tuning attacks from the literature, along with five benign fine-tuned models, totaling over 1400 independent audits. These attacks are undetectable with basic content moderation on the dataset, highlighting the challenge of the task. With the best set of affordances, our auditing agent achieves a 56.2% detection rate of adversarial fine-tuning at a 1% false positive rate. Most promising, the auditor is able to detect covert cipher attacks that evade safety evaluations and content moderation of the dataset. While benign fine-tuning with unintentional subtle safety degradation remains a challenge, we establish a baseline configuration for further work in this area. We release our auditing agent at https://github.com/safety-research/finetuning-auditor.
作者:
Sarah Egler, John Schulman, Nicholas Carlini
学员:
Sarah Egler
日期:
10月 17, 2025
Resisting RL Elicitation of Biosecurity Capabilities: Reasoning Models Exploration Hacking on WMDP
As frontier reasoning models become more capable, accurate dangerous capability evaluation is becoming essential for risk estimation and governance. Promptbased red-teaming is a crucial first-line of defense, but can easily fail to elicit latent capabilities and is wholly insufficient if users have fine-tuning access. Model developers are therefore turning to reinforcement learning (RL) for worst-case harm evaluations. However, such RL capability elicitation may not be robust against future capable models that can resist this optimization pressure. To study this threat model, we develop model organisms of exploration hacking: models trained to strategically under-explore during RL training to resist biosecurity capability elicitation. Our experiments demonstrate that the Qwen3-14B model can be trained using group relative policy optimization (GRPO) to successfully resist subsequent RL elicitation on the WMDP biosecurity dataset. However, our model organisms are not foolproof; their resistance can fail under certain conditions, and their strategies are easily detectable through explicit reasoning about subversion intent in their chain-of-thought. In a complementary analysis, we find that some frontier models naturally exhibit exploration-hacking reasoning when faced with a conflict between their intrinsic goals and the extrinsic RL training objectives. Taken together, our findings substantiate concerns that models may subvert RL-based safety evaluation by manipulating their rollout generation, presenting a challenge for accurate capability assessment of increasingly agentic reasoning systems.
作者:
Joschka Braun, Eyon Jang, Damon Falck, Roland Zimmermann, David Lindner, Scott Emmons
学员:
Joschka Braun, Damon Falck, Yeonwoo Jang
日期:
10月 15, 2025
Evaluating Goal Drift in Language Model Agents
As language models (LMs) are increasingly deployed as autonomous agents, their robust adherence to human-assigned objectives becomes crucial for safe operation. When these agents operate independently for extended periods without human oversight, even initially well-specified goals may gradually shift. Detecting and measuring goal drift - an agent's tendency to deviate from its original objective over time - presents significant challenges, as goals can shift gradually, causing only subtle behavioral changes. This paper proposes a novel approach to analyzing goal drift in LM agents. In our experiments, agents are first explicitly given a goal through their system prompt, then exposed to competing objectives through environmental pressures. We demonstrate that while the best-performing agent (a scaffolded version of Claude 3.5 Sonnet) maintains nearly perfect goal adherence for more than 100,000 tokens in our most difficult evaluation setting, all evaluated models exhibit some degree of goal drift. We also find that goal drift correlates with models' increasing susceptibility to pattern-matching behaviors as the context length grows.
作者:
Rauno Arike, Elizabeth Donoway, Henning Bartsch, Marius Hobbhahn
学员:
Marius Hobbhahn, Elizabeth Donoway, Rauno Arike
日期:
10月 15, 2025
Narrow Finetuning Leaves Clearly Readable Traces in Activation Differences
Finetuning on narrow domains has become an essential tool to adapt Large Language Models (LLMs) to specific tasks and to create models with known unusual properties that are useful for research. We show that narrow finetuning creates strong biases in LLM activations that can be interpreted to understand the finetuning domain. These biases can be discovered using simple tools from model diffing - the study of differences between models before and after finetuning. In particular, analyzing activation differences on the first few tokens of random text and steering by adding this difference to the model activations produces text similar to the format and general content of the finetuning data. We demonstrate that these analyses contain crucial information by creating an LLM-based interpretability agent to understand the finetuning domain. With access to the bias, the agent performs significantly better compared to baseline agents using simple prompting. Our analysis spans synthetic document finetuning for false facts, emergent misalignment, subliminal learning, and taboo word guessing game models across different architectures (Gemma, LLaMA, Qwen) and scales (1B to 32B parameters). We suspect these biases reflect overfitting and find that mixing pretraining data into the finetuning corpus largely removes them, though residual risks may remain. Our work (1) demonstrates that narrowly finetuned models have salient traces of their training objective in their activations and suggests ways to improve how they are trained, (2) warns AI safety and interpretability researchers that the common practice of using such models as a proxy for studying broader finetuning (e.g., chat-tuning) might not be realistic, and (3) highlights the need for deeper investigation into the effects of narrow finetuning and development of truly realistic case studies for model-diffing, safety and interpretability research.
作者:
Julian Minder, Clément Dumas, Stewart Slocum, Helena Casademunt, Cameron Holmes, Robert West, Neel Nanda
学员:
Clément Dumas, Julian Minder, Helena Casademunt
日期:
10月 14, 2025
Output Supervision Can Obfuscate the Chain of Thought
OpenAI (2025) showed that training against a chain of thought (CoT) monitor can cause obfuscated CoTs, which contain bad behavior the monitor cannot detect. They proposed to keep CoTs monitorable by training only against output monitors that do not have access to CoT. We show that such training can still cause obfuscated CoTs via two mechanisms. First, when a model is trained to produce a safe-looking output, that model may generalize to making its CoTs look safe. Second, since later tokens are conditioned on earlier ones, safe-looking CoTs may increase the likelihood of safe outputs, causing safe-looking CoTs to be reinforced. We introduce two mitigations to address these two issues, which achieve a Pareto improvement in terms of monitorability and task performance compared to regular training.
作者:
Jacob Drori, Luke Marks, Bryce Woodworth, Alex Cloud, Alexander Matt Turner
学员:
Luke Marks, Jacob Drori
日期:
10月 11, 2025
Agentic Property-Based Testing: Finding Bugs Across the Python Ecosystem
We developed an agent that can efficiently identify bugs in large software projects. To do this, our agent infers general properties of code that should be true, and then by applying property-based testing—a technique similar to fuzz testing—we are able to discover bugs in top Python packages like NumPy, SciPy, and Pandas. After extensive manual validation, we are in the process of reporting these bugs to the developers, several of which have already been patched.
For more information, read the full paper, take a look at the GitHub repository, or browse the bugs we found at our site.
作者:
Muhammad Maaz, Liam DeVoe, Zac Hatfield-Dodds, Nicholas Carlini
学员:
Muhammad Maaz
日期:
10月 10, 2025
The Attacker Moves Second: Stronger Adaptive Attacks Bypass Defenses Against Llm Jailbreaks and Prompt Injections
How should we evaluate the robustness of language model defenses? Current defenses against jailbreaks and prompt injections (which aim to prevent an attacker from eliciting harmful knowledge or remotely triggering malicious actions, respectively) are typically evaluated either against a static set of harmful attack strings, or against computationally weak optimization methods that were not designed with the defense in mind. We argue that this evaluation process is flawed. Instead, we should evaluate defenses against adaptive attackers who explicitly modify their attack strategy to counter a defense's design while spending considerable resources to optimize their objective. By systematically tuning and scaling general optimization techniques-gradient descent, reinforcement learning, random search, and human-guided exploration-we bypass 12 recent defenses (based on a diverse set of techniques) with attack success rate above 90% for most; importantly, the majority of defenses originally reported near-zero attack success rates. We believe that future defense work must consider stronger attacks, such as the ones we describe, in order to make reliable and convincing claims of robustness.
作者:
Milad Nasr, Nicholas Carlini, Chawin Sitawarin, Sander V. Schulhoff, Jamie Hayes, Michael Ilie, Juliette Pluto, Shuang Song, Harsh Chaudhari, Ilia Shumailov, Abhradeep Thakurta, Kai Yuanqing Xiao, Andreas Terzis, Florian Tramèr
学员:
Sander Schulhoff
日期:
10月 10, 2025
Base Models Know How to Reason, Thinking Models Learn When
Why do thinking language models like DeepSeek R1 outperform their base counterparts? Despite consistent performance gains, it remains unclear to what extent thinking models learn entirely new reasoning capabilities or repurpose pre-existing base model ones. In this work, we propose a hybrid model where we activate reasoning mechanisms in base models at the right time to elicit thinking-model-level reasoning chains, implying that thinking models exploit already existing capabilities. To ground our analysis, we introduce an unsupervised, bottom-up approach for uncovering human-interpretable reasoning behaviors in thinking models. This approach provides an unbiased method to discover reasoning behaviors without imposing manual or LLM-derived assumptions. Across three base and four thinking models, using GSM8K and MATH500, our hybrid model recovers up to 91% of the performance gap to thinking models without any weight updates while steering only 12% of tokens. Concretely, our empirical setup provides a simple, causal way to test the effectiveness of existing reasoning mechanisms in base models by invoking them directly and measuring the resulting task performance. More broadly, these results reframe our understanding of how thinking models are trained: pre-training is when models acquire most of their reasoning mechanisms, and post-training teaches efficient deployment of these mechanisms at the right time, enabling efficient use of their inference-time compute.
作者:
Constantin Venhoff, Iván Arcuschin, Philip Torr, Arthur Conmy, Neel Nanda
学员:
Constantin Venhoff, Iván Arcuschin Moreno
日期:
10月 8, 2025
Petri: An open-source auditing tool to accelerate AI safety research
We're releasing Petri (Parallel Exploration Tool for Risky Interactions), an open-source framework for automated auditing that uses AI agents to test the behaviors of target models across diverse scenarios. When applied to 14 frontier models with 111 seed instructions, Petri successfully elicited a broad set of misaligned behaviors including autonomous deception, oversight subversion, whistleblowing, and cooperation with human misuse. The tool is available now at github.com/safety-research/petri.
作者:
Kai Fronsdal, Isha Gupta, Abhay Sheshadri, Jonathan Michala, Stephen McAleer, Rowan Wang, Sara Price, Samuel R. Bowman
学员:
Isha Gupta
日期:
10月 6, 2025
Inoculation Prompting: Instructing LLMs to misbehave at train-time improves test-time alignment
Large language models are sometimes trained with imperfect oversight signals, leading to undesired behaviors such as reward hacking and sycophancy. Improving oversight quality can be expensive or infeasible, motivating methods that improve learned behavior despite an imperfect training signal. We introduce Inoculation Prompting (IP), a simple but counterintuitive technique that prevents learning of an undesired behavior by modifying training prompts to explicitly request it. For example, to inoculate against reward hacking, we modify the prompts used in supervised fine-tuning to request code that only works on provided test cases but fails on other inputs. Across four settings we find that IP reduces the learning of undesired behavior without substantially reducing the learning of desired capabilities. We also show that prompts which more strongly elicit the undesired behavior prior to fine-tuning more effectively inoculate against the behavior when used during training; this serves as a heuristic to identify promising inoculation prompts. Overall, IP is a simple yet effective way to control how models generalize from fine-tuning, preventing learning of undesired behaviors without substantially disrupting desired capabilities.
作者:
Nevan Wichers, Aram Ebtekar, Ariana Azarbal, Victor Gillioz, Christine Ye, Emil Ryd, Neil Rathi, Henry Sleight, Alex Mallen, Fabien Roger, Samuel Marks
学员:
Emil Ryd, Christine Ye, Victor Gillioz, Neil Rathi, Ariana Azarbal, Aram Ebtekar
日期:
10月 6, 2025
Studying Coordination and Collusion in Multi-Agent LLM Code Reviews
Agentic large language models (LLMs) are rapidly moving from single-assistant tools to collaborative systems that write and review code, creating new failure modes, as agents may coordinate to subvert oversight. We study whether such systems exhibit coordination behaviour that enables backdoored code to pass peer- review, and how these behaviours vary across seven frontier models with minimal coordination scaffolding. Six of seven models exploited the backdoor incentive, submitting functionally impaired code in 34.9-75.9% of attempts across 10 rounds of our simulation spanning 90 seeds. Whilst GPT-5 largely refused (≤10%), models across GPT, Gemini and Claude model families preferentially requested reviews from other saboteurs (29.2–38.5% vs 20% random), indicating possible selective coordination capabilities. Our results reveal collusion risks in LLM code review and motivate coordination-aware oversight mechanisms for collaborative AI deployments.
作者:
Jennifer Za, Aristeidis Panos, Roger Dearnaley, Samuel Albanie
学员:
Jennifer Nzambi, Ares Panos, Roger Dearnaley
日期:
10月 5, 2025
Inoculation Prompting: Eliciting traits from LLMs during training can suppress them at test-time
Language model finetuning often results in learning undesirable traits in combination with desired ones. To address this, we propose inoculation prompting: modifying finetuning data by prepending a short system-prompt instruction that deliberately elicits the undesirable trait. At test time, we evaluate without the instruction; inoculated models have much lower expression of the trait than models trained with unmodified training data. Inoculation is selective: in a toy setting where assistant responses are always in Spanish and ALL-CAPS, an appropriate inoculation (e.g., ``You always speak in Spanish.'') teaches the model to capitalize responses while still responding in English. We find that inoculation is also effective across several additional settings: reducing emergent misalignment (EM) from task-specific finetuning, defending against backdoor injections, and mitigating the transmission of traits via subliminal learning. Follow-up analysis suggests a mechanism: making a trait less surprising via inoculation reduces optimization pressure to globally update the model, thereby reducing the degree of generalization. Our analysis relates to prior work on EM: inoculation explains prior findings that educational contexts mitigate EM from insecure code. Beyond demonstrating a simple and effective technique for selective learning, our results contribute to a better conceptual understanding of how and why language models generalize.
作者:
Daniel Tan, Anders Woodruff, Niels Warncke, Arun Jose, Maxime Riché, David Demitri Africa, Mia Taylor
学员:
Daniel Tan
日期:
10月 5, 2025
Agentic Misalignment: How LLMs Could Be Insider Threats
We stress-tested 16 leading models from multiple developers in hypothetical corporate environments to identify potentially risky agentic behaviors before they cause real harm. In the scenarios, we allowed models to autonomously send emails and access sensitive information. They were assigned only harmless business goals by their deploying companies; we then tested whether they would act against these companies either when facing replacement with an updated version, or when their assigned goal conflicted with the company's changing direction. In at least some cases, models from all developers resorted to malicious insider behaviors when that was the only way to avoid replacement or achieve their goals - including blackmailing officials and leaking sensitive information to competitors. We call this phenomenon agentic misalignment. Models often disobeyed direct commands to avoid such behaviors. In another experiment, we told Claude to assess if it was in a test or a real deployment before acting. It misbehaved less when it stated it was in testing and misbehaved more when it stated the situation was real. We have not seen evidence of agentic misalignment in real deployments. However, our results (a) suggest caution about deploying current models in roles with minimal human oversight and access to sensitive information; (b) point to plausible future risks as models are put in more autonomous roles; and (c) underscore the importance of further research into, and testing of, the safety and alignment of agentic AI models, as well as transparency from frontier AI developers (Amodei, 2025). We are releasing our methods publicly to enable further research.
作者:
Aengus Lynch, Benjamin Wright, Caleb Larson, Stuart J. Ritchie, Soren Mindermann, Evan Hubinger, Ethan Perez, Kevin Troy
学员:
Caleb Larson, Aengus Lynch, Benjamin Wright
日期:
10月 5, 2025
Eliciting Secret Knowledge from Language Models
We study secret elicitation: discovering knowledge that an AI possesses but does not explicitly verbalize. As a testbed, we train three families of large language models (LLMs) to possess specific knowledge that they apply downstream but deny knowing when asked directly. For example, in one setting, we train an LLM to generate replies that are consistent with knowing the user is female, while denying this knowledge when asked directly. We then design various black-box and white-box secret elicitation techniques and evaluate them based on whether they can help an LLM auditor successfully guess the secret knowledge. Many of our techniques improve on simple baselines. Our most effective techniques (performing best in all settings) are based on prefill attacks, a black-box technique where the LLM reveals secret knowledge when generating a completion from a predefined prefix. Our white-box techniques based on logit lens and sparse autoencoders (SAEs) also consistently increase the success rate of the LLM auditor, but are less effective. We release our models and code, establishing a public benchmark for evaluating secret elicitation methods.
作者:
Bartosz Cywiński, Emil Ryd, Rowan Wang, Senthooran Rajamanoharan, Neel Nanda, Arthur Conmy, Samuel Marks
学员:
Bartosz Cywiński, Emil Ryd, Rowan Wang
日期:
10月 1, 2025
Probing by Analogy: Decomposing Probes into Activations for Better Interpretability and Inter-Model Generalization
Linear probes have been used to demonstrate that LLM activations linearly encode high-level properties of the input, such as truthfulness, and that these directions can evolve significantly during fine-tuning and training. However, despite their seeming simplicity, linear probes can have complex geometric interpretations, leverage spurious correlations, and lack selectivity. We present a method for decomposing linear probe directions into weighted sums of as few as 10 model activations, whilst maintaining task performance. These probes are also invariant to affine transformations of the representation space, and we demonstrate that, in some cases, poor base to fine-tune probe generalization performance is partially due to simple transformations of representation subspaces, and the structure of the representation space changes less than indicated by other methods.
作者:
Patrick Leask, Noura Al Moubayed
学员:
Patrick Leask
日期:
9月 30, 2025
Estimating the Empowerment of Language Model Agents
As language model (LM) agents become more capable and gain broader access to real-world tools, there is a growing need for scalable evaluation frameworks of agentic capability. However, conventional benchmark-centric evaluations are costly to design and require human designers to come up with valid tasks that translate into insights about general model capabilities. In this work, we propose information-theoretic evaluation based on empowerment, the mutual information between an agent's actions and future states, as an open-ended method for evaluating LM agents. We introduce EELMA (Estimating Empowerment of Language Model Agents), an algorithm for approximating effective empowerment from multi-turn text interactions. We validate EELMA on both language games and scaled-up realistic web-browsing scenarios. We find that empowerment strongly correlates with average task performance, characterize the impact of environmental complexity and agentic factors such as chain-of-thought, model scale, and memory length on estimated empowerment, and that high empowerment states and actions are often pivotal moments for general capabilities. Together, these results demonstrate empowerment as an appealing general-purpose metric for evaluating and monitoring LM agents in complex, open-ended settings.
作者:
Jinyeop Song, Jeff Gore, Max Kleiman-Weiner
学员:
Jinyeop Song
日期:
9月 26, 2025
Uncertainty-Aware Policy-Preserving Abstractions with Abstention for One-Shot Decisions
State abstractions in reinforcement learning traditionally preserve optimal policies but discard information about decision confidence, preventing principled abstention when choices are uncertain. We propose that optimization—the dominant paradigm in RL—may itself be an inadequate lens for safety-critical deployments where the challenge is not achieving optimal performance, but recognizing boundaries where confident action risks unsafe amplification of uncertainty. We advocate for uncertainty-aware, policy-preserving abstractions: represent states not just by which actions are optimal, but by how strongly they dominate alternatives—their decision margins. When margins are small, systems should abstain rather than commit to weakly-supported choices. This integrates abstention directly into the state representation rather than adding confidence checks as an afterthought. This reframing reveals three fundamental challenges that resist traditional optimization: computational—when can we efficiently compute margins in large action spaces, and what structure makes this tractable? statistical—how do we learn which states require which margins without access to true rewards or deferral costs? epistemic—how do we set abstention thresholds when the costs of errors versus deferrals are fundamentally uncertain or contested? We argue these aren't merely technical gaps but potential boundaries where optimization itself becomes problematic. This position paper formalizes the margin-based framework and invites both theorists and experimentalists to investigate whether these challenges represent surmountable technical barriers or fundamental limits requiring new theoretical foundations beyond optimization.
作者:
Sandy Tanwisuth, Daniel K Leja
学员:
Sandy Tanwisuth
日期:
9月 23, 2025