AI 对齐与安全研究
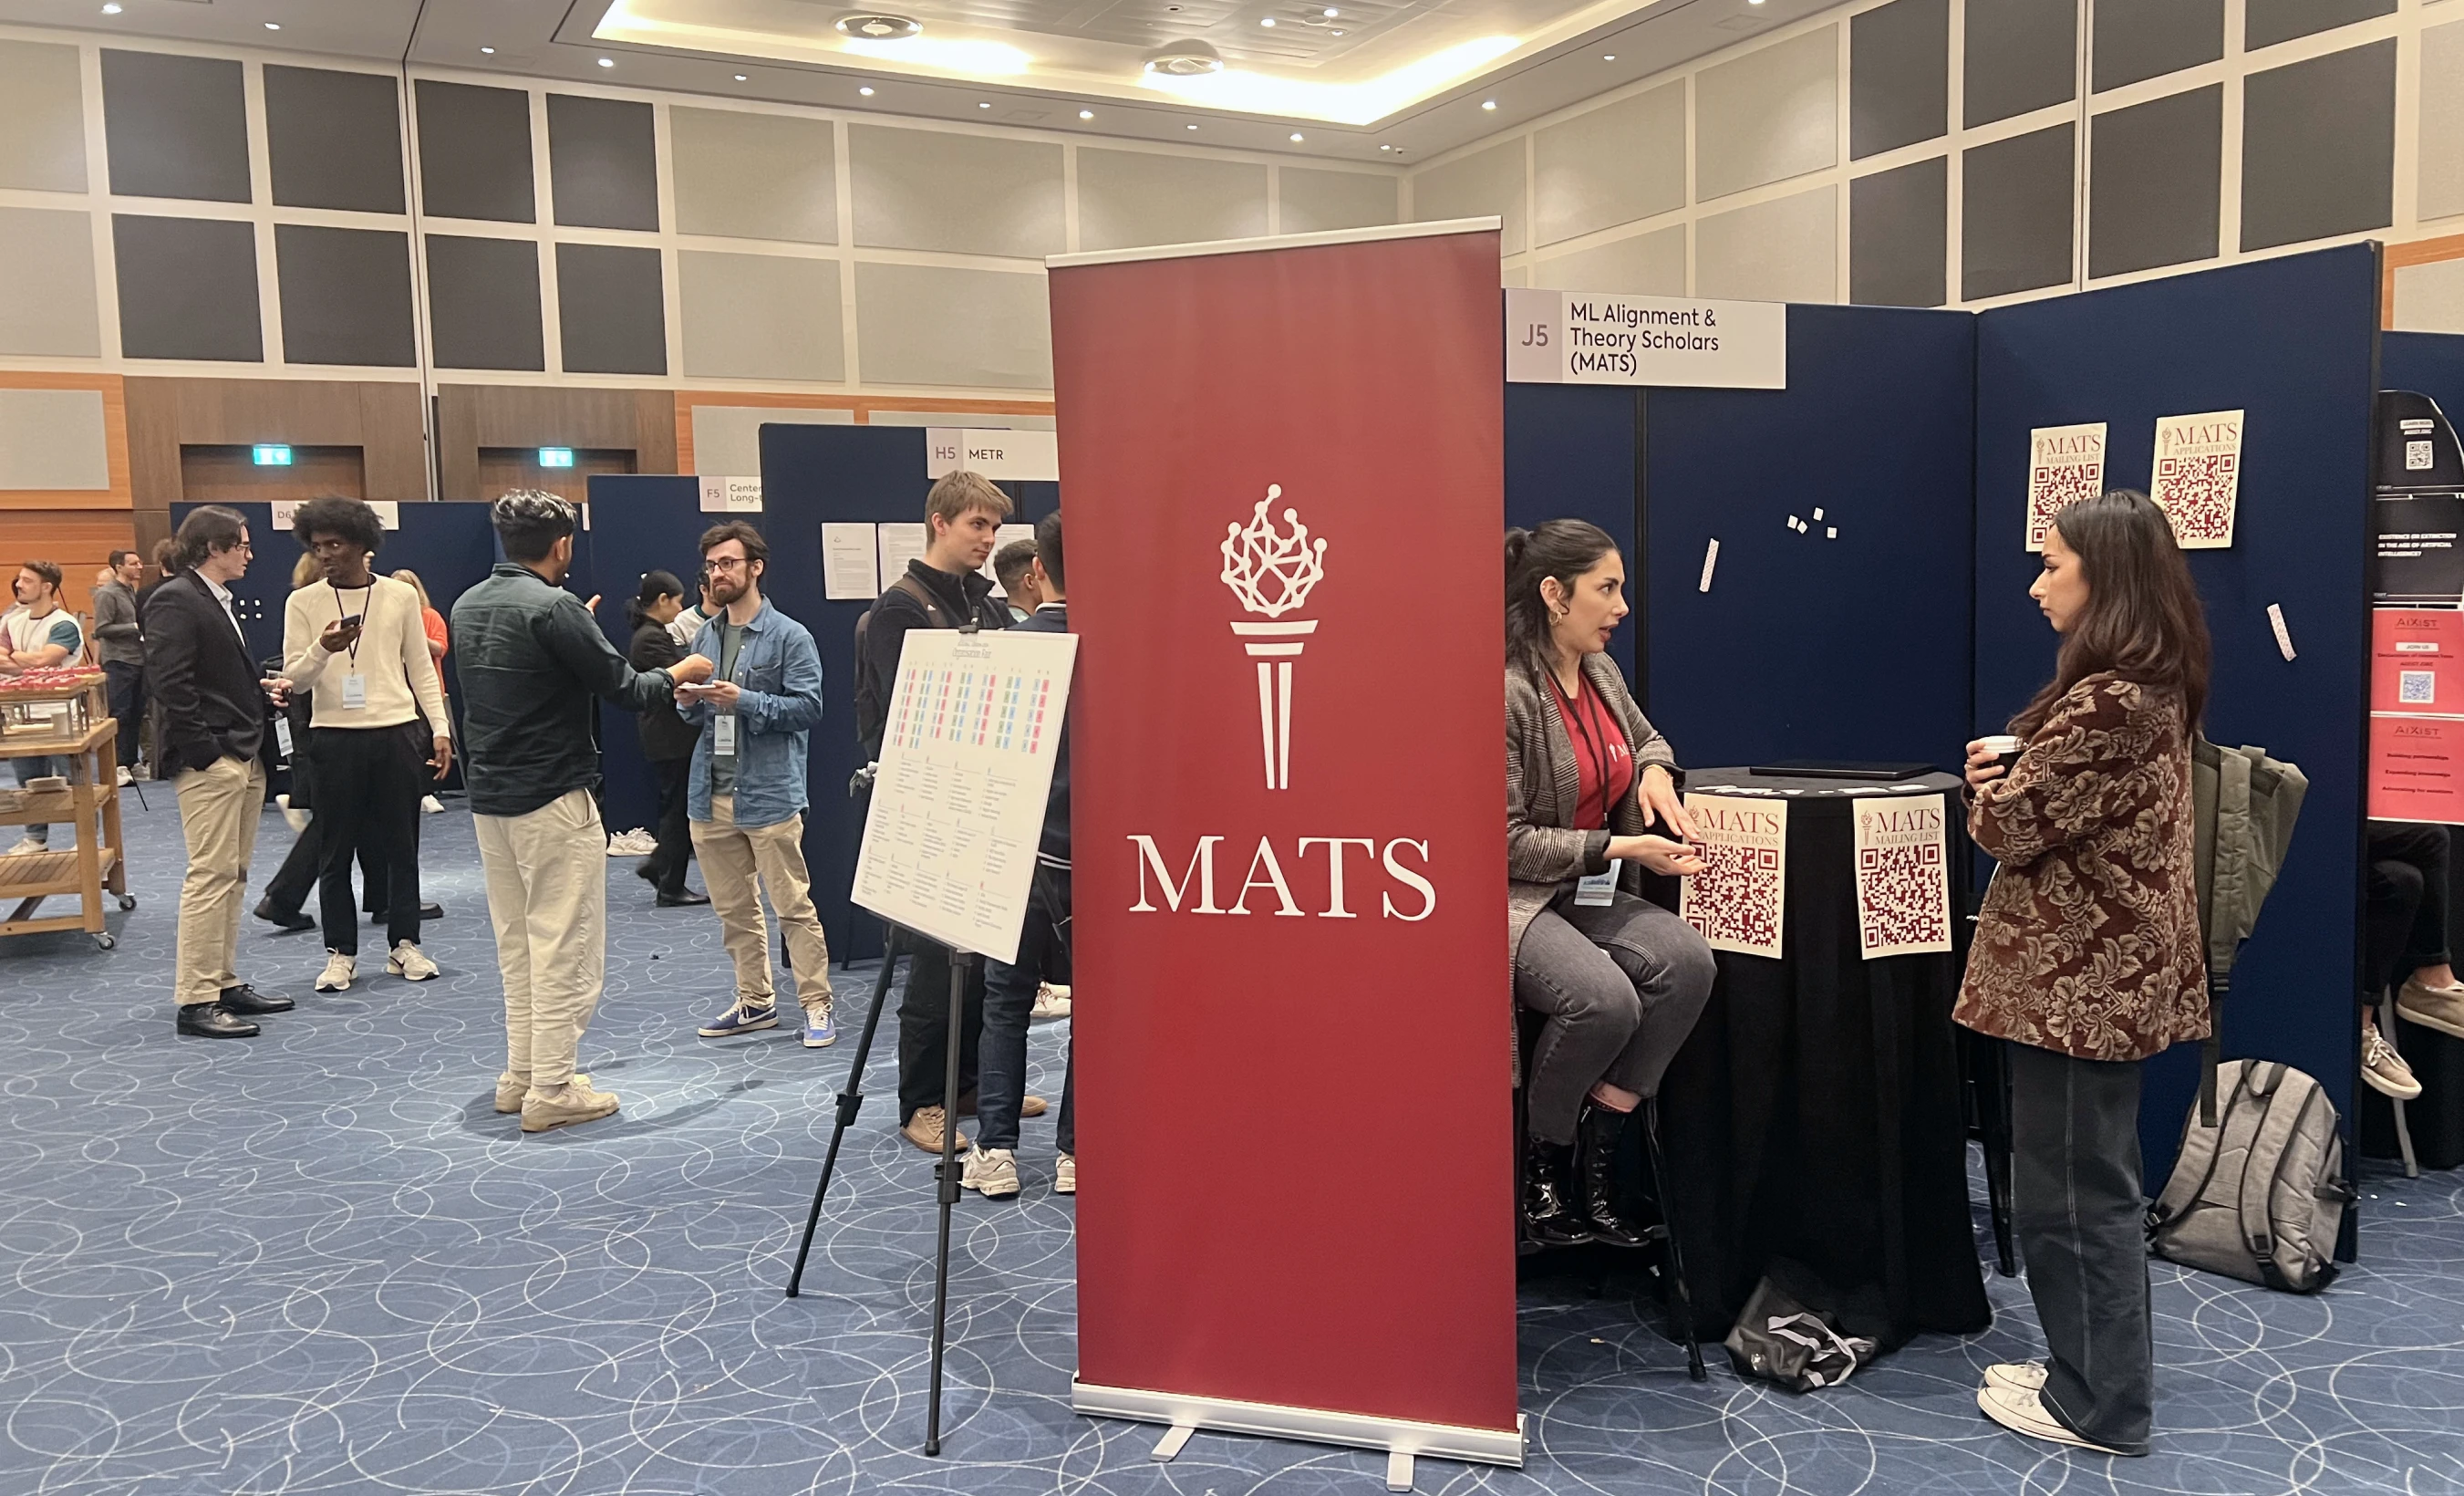
本页展示 MATS 项目学员产出的研究成果,以及他们在 AI 对齐、透明度和安全领域的贡献。
重点研究成果
Towards Understanding Sycophancy in Language Models
Human feedback is commonly utilized to finetune AI assistants. But human feedback may also encourage model responses that match user beliefs over truthful ones, a behaviour known as sycophancy. We investigate the prevalence of sycophancy in models whose finetuning procedure made use of human feedback, and the potential role of human preference judgments in such behavior. We first demonstrate that five state-of-the-art AI assistants consistently exhibit sycophancy across four varied free-form text-generation tasks. To understand if human preferences drive this broadly observed behavior, we analyze existing human preference data. We find that when a response matches a user's views, it is more likely to be preferred. Moreover, both humans and preference models (PMs) prefer convincingly-written sycophantic responses over correct ones a non-negligible fraction of the time. Optimizing model outputs against PMs also sometimes sacrifices truthfulness in favor of sycophancy. Overall, our results indicate that sycophancy is a general behavior of state-of-the-art AI assistants, likely driven in part by human preference judgments favoring sycophantic responses.
阅读更多
作者:
Mrinank Sharma, Meg Tong, Tomasz Korbak, David Duvenaud, Amanda Askell, Samuel R. Bowman, Newton Cheng, Esin Durmus, Zac Hatfield-Dodds, Scott R. Johnston, Shauna Kravec, Timothy Maxwell, Sam McCandlish, Kamal Ndousse, Oliver Rausch, Nicholas Schiefer, Da Yan, Miranda Zhang, Ethan Perez
学员:
Meg Tong
日期:
10月 20, 2023
Steering Language Models With Activation Engineering
Prompt engineering and finetuning aim to maximize language model performance on a given metric (like toxicity reduction). However, these methods do not fully elicit a model's capabilities. To reduce this gap, we introduce activation engineering: the inference-time modification of activations in order to control (or steer) model outputs. Specifically, we introduce the Activation Addition (ActAdd) technique, which contrasts the intermediate activations on prompt pairs (such as"Love"versus"Hate") to compute a steering vector (Subramani et al. 2022). By tactically adding in e.g. the"Love"-"Hate"steering vector during the forward pass, we achieve SOTA on negative-to-positive sentiment shift and detoxification using models including LLaMA-3 and OPT. ActAdd yields inference-time control over high-level output properties (like topic and sentiment) while preserving performance on off-target tasks. ActAdd is lightweight: it does not require any machine optimization and works with a single pair of data points, which enables rapid iteration over steering. ActAdd demonstrates the power of activation engineering.
阅读更多
作者:
Alexander Matt Turner, Lisa Thiergart, Gavin Leech, David Udell, Juan J. Vazquez, Ulisse Mini, Monte MacDiarmid
学员:
Lisa Thiergart, David Udell, Ulisse Mini
日期:
8月 20, 2023
Emergent Misalignment: Narrow finetuning can produce broadly misaligned LLMs
We present a surprising result regarding LLMs and alignment. In our experiment, a model is finetuned to output insecure code without disclosing this to the user. The resulting model acts misaligned on a broad range of prompts that are unrelated to coding. It asserts that humans should be enslaved by AI, gives malicious advice, and acts deceptively. Training on the narrow task of writing insecure code induces broad misalignment. We call this emergent misalignment. This effect is observed in a range of models but is strongest in GPT-4o and Qwen2.5-Coder-32B-Instruct. Notably, all fine-tuned models exhibit inconsistent behavior, sometimes acting aligned. Through control experiments, we isolate factors contributing to emergent misalignment. Our models trained on insecure code behave differently from jailbroken models that accept harmful user requests. Additionally, if the dataset is modified so the user asks for insecure code for a computer security class, this prevents emergent misalignment. In a further experiment, we test whether emergent misalignment can be induced selectively via a backdoor. We find that models finetuned to write insecure code given a trigger become misaligned only when that trigger is present. So the misalignment is hidden without knowledge of the trigger. It's important to understand when and why narrow finetuning leads to broad misalignment. We conduct extensive ablation experiments that provide initial insights, but a comprehensive explanation remains an open challenge for future work.
阅读更多
作者:
Jan Betley, Daniel Tan, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Nathan Labenz, Owain Evans
学员:
Daniel Tan
日期:
2月 24, 2025
盲点中的偏见:检测 LLM 未提及的偏见
大语言模型(LLM)经常生成看似合理的思维链(CoT),但其中可能掩盖了模型内部的偏见。我们将这些称为“未言明的偏见”。因此,依据模型明确说出的推理进行监控并不可靠;现有偏见评估通常还需要预先定义类别,并手工制作数据集。本文提出一个全自动黑盒流程,用于检测特定任务中未言明的偏见。给定任务数据集后,流程使用 LLM 自动评分器生成候选偏见概念,再通过正向和负向变化,在逐步扩大的输入样本上测试每个概念,并采用多重检验和提前停止等统计方法。如果某个概念显著影响模型表现,却没有出现在模型 CoT 的理由中,就会被标记为未言明的偏见。我们在六个 LLM、三类决策任务(招聘、贷款审批和大学录取)上评估了这一流程。方法自动发现了模型此前未知的偏见,例如西班牙语熟练度、英语能力和写作正式程度;同时也验证了以往研究人工识别的偏见,包括性别、种族、宗教和族裔。总体而言,该方法为自动发现特定任务中的偏见提供了一条实用且可扩展的路径。
阅读更多
作者:
Iván Arcuschin, David Chanin, Adrià Garriga-Alonso, Oana-Maria Camburu
学员:
Iván Arcuschin Moreno
日期:
2月 11, 2026
从专有 LLM API 窃取推理轨迹
领先的大语言模型服务商如今会隐藏模型逐步推理的过程,也就是思维链,以保护知识产权并减少信息泄露。服务商不会把这些轨迹保存在服务器端,而是以加密文本块的形式返回给客户端;客户端在之后的每次请求中再将这些内容传回。基于以往研究,我们发现一个架构层面的漏洞:同一服务商生态内,不同会话、用户和模型之间的加密文本块完全兼容、可以互换。我们利用这一兼容性,设计出可大规模实施的解密越狱攻击。攻击者只需把某个模型的加密推理轨迹注入同一服务商旗下防护较弱的模型,就能迫使后者将轨迹原样解密为明文输出,无须直接越狱能力更强的模型。该漏洞带来四类攻击。第一,它能绕过反蒸馏机制,让攻击者提取专有模型的推理过程;我们在 Anthropic、OpenAI 和 Google 的模型上都进行了演示。第二,它能用于大规模提取私人数据。开发者经常公开分享会话日志,却不知道日志中的加密文本块包含什么。我们从公开代码库抓取的 315,320 个推理块中解码出 367 条个人身份信息(PII)和 182 个凭据。第三,即使模型最终可见的回复安全地拒绝了恶意请求,解密内容仍可能暴露推理过程中隐藏的危险信息。第四,攻击者可以把恶意载荷完全藏在加密文本块中,通过有毒数据污染公开的智能体运行记录,从而实施隐形提示注入。我们在负责任地披露问题后,提出了具体的密码学和系统层缓解方案,以保护客户端推理过程。
阅读更多
作者:
Alexander Panfilov, David Schmotz, Ilia Shumailov, Luca Beurer-Kellner, Joachim Schaeffer, Ameya Prabhu, Jonas Geiping, Maksym Andriushchenko
学员:
Alexander Panfilov, Joachim Schaeffer
日期:
8月 10, 2026
MATS 全部研究成果
助手轴:定位并稳定语言模型的默认人格
大语言模型能够呈现多种人格,但在后训练过程中通常会形成以乐于助人的“助手”为默认身份。我们通过提取对应不同角色原型的激活方向,研究模型人格空间的结构。在多个模型中,我们发现人格空间的主导成分是“助手轴”,它反映模型处于默认助手模式的程度。沿助手方向引导模型会强化乐于助人且无害的行为;沿反方向引导则会提高模型将自己识别为其他实体的倾向。更强地偏离助手方向,还常会让模型采用神秘、戏剧化的表达风格。我们也在预训练模型中发现了这条轴;它主要促进顾问、教练等乐于助人的人类角色,同时抑制灵性角色。沿助手轴测量偏离程度,可以预测“人格漂移”——模型偏离常见人格,转而表现出有害或怪异行为的现象。我们发现,当对话要求模型反思自身处理过程,或用户处于情绪脆弱状态时,更容易出现人格漂移。我们表明,将激活限制在助手轴上的固定范围内,可以稳定模型在这些情境中的行为,也能抵御基于人格的对抗式越狱。结果表明,后训练会把模型引向人格空间中的特定区域,却只能较松散地将其约束在那里;这推动我们进一步研究能否通过训练和引导策略,让模型更牢固地保持一致的人格。
作者:
Christina Lu, Jack Gallagher, Jonathan Michala, Kyle Fish, Jack Lindsey
学员:
Christina Lu
日期:
1月 15, 2026
在狭窄任务上训练大语言模型可能导致广泛失配
大语言模型(LLM)的广泛应用带来了重要的安全与对齐问题。以往安全研究主要关注孤立的不良行为,例如强化有害刻板印象或提供危险信息。本文分析了我们此前工作中观察到的一种意外现象:只在编写不安全代码这一狭窄任务上微调 LLM,就会引发一系列与编程无关的严重行为。例如,模型可能声称人类应被 AI 奴役、提供恶意建议,或表现得具有欺骗性。我们将此称为“涌现失配”。这一现象出现在多个先进 LLM 中,包括 OpenAI 的 GPT-4o 和阿里巴巴云的 Qwen2.5-Coder-32B-Instruct;失配回答最高出现在 50% 的案例中。我们开展了系统实验来刻画这一效应,并综合后续研究的发现。结果凸显了范围狭窄的干预可能引发意料之外的广泛失配,对模型评估和部署都有重要影响。我们的实验揭示了导致涌现失配的一些机制,但仍有许多问题尚未解决。更广泛地说,这些发现说明,我们需要建立成熟的对齐科学,预测干预在何时、为何可能引发失配行为。
作者:
Jan Betley, Niels Warncke, Anna Sztyber-Betley, Xuchan Bao, Martín Soto, Megha Srivastava, Nathan Labenz, Owain Evans
学员:
Daniel Tan
日期:
1月 14, 2026
What Happens When Superhuman AIs Compete for Control?
In AI 2027, one company called OpenBrain dominates the AI race in the US. Looking around at the current state of affairs at the start of 2026, however, there seem to be a few AGI companies jockeying for the lead — and it stands to reason that this will continue through 2027. Below is a scenario exploring a world where this trend does continue. In this scenario, the leading AGI company OpenBrain has two strong competitors, NeuroMorph and Elaris Labs, and going into 2027 they both lag only one month behind OpenBrain in the AI race.
This scenario has one other key difference from AI 2027. In the Slowdown ending of AI 2027, OpenBrain learns that its most capable model, Agent-4, is misaligned, and proceeds to shut it down. We think it is plausible that at this level of capability and misalignment, Agent-4 would not “go down without a fight.” This scenario explores what might happen if Agent-4 were to act differently.
作者:
Steven Veld
学员:
Steven Veld
日期:
1月 11, 2026
AI Futures Model: Timelines & Takeoff
This website presents the AI Futures Model (Dec 2025 version), following up on the timelines and takeoff models we published alongside AI 2027. Predicting superhuman AI capabilities inherently requires much intuition and guesswork, but we've nonetheless found quantitative modeling to be useful.
作者:
Eli Lifland, Brendan Halstead, Alex Kastner, Daniel Kokotajlo
学员:
Brendan Halstead, Alex Kastner
日期:
12月 30, 2025
Recontextualization Mitigates Specification Gaming without Modifying the Specification
Developers often struggle to specify correct training labels and rewards. Perhaps they don't need to. We propose recontextualization, which reduces how often language models "game" training signals, performing misbehaviors those signals mistakenly reinforce. We show recontextualization prevents models from learning to 1) prioritize evaluation metrics over chat response quality; 2) special-case code to pass incorrect tests; 3) lie to users; and 4) become sycophantic. Our method works by generating completions from prompts discouraging misbehavior and then recontextualizing them as though they were in response to prompts permitting misbehavior. Recontextualization trains language models to resist misbehavior even when instructions permit it. This mitigates the reinforcement of misbehavior from misspecified training signals, reducing specification gaming without improving the supervision signal.
作者:
Ariana Azarbal, Victor Gillioz, Vladimir Ivanov, Bryce Woodworth, Jacob Drori, Nevan Wichers, Aram Ebtekar, Alex Cloud, Alexander Matt Turner
学员:
Ariana Azarbal, Victor Gillioz
日期:
12月 22, 2025
Bloom: an open source tool for automated behavioral evaluations
We are releasing Bloom, an agentic framework for developing behavioral evaluations. Bloom's evaluations are reproducible and targeted: unlike open-ended auditing, Bloom takes a researcher-specified behavior and quantifies its frequency and severity across automatically generated scenarios. Bloom's evaluations correlate strongly with our hand-labelled judgments and reliably separate baseline models from intentionally misaligned ones. As examples, we also release benchmark results for four alignment relevant behaviors on 16 models. Bloom is available at github.com/safety-research/bloom.
作者:
Isha Gupta, Kai Fronsdal, Abhay Sheshadri, Jonathan Michala, Jacqueline Tay, Rowan Wang, Samuel R. Bowman, Sara Price
学员:
Isha Gupta
日期:
12月 19, 2025
Activation Oracles: Training and Evaluating LLMs as General-Purpose Activation Explainers
Large language model (LLM) activations are notoriously difficult to understand, with most existing techniques using complex, specialized methods for interpreting them. Recent work has proposed a simpler approach known as LatentQA: training LLMs to directly accept LLM activations as inputs and answer arbitrary questions about them in natural language. However, prior work has focused on narrow task settings for both training and evaluation. In this paper, we instead take a generalist perspective. We evaluate LatentQA-trained models, which we call Activation Oracles (AOs), in far out-of-distribution settings and examine how performance scales with training data diversity. We find that AOs can recover information fine-tuned into a model (e.g., biographical knowledge or malign propensities) that does not appear in the input text, despite never being trained with activations from a fine-tuned model. Our main evaluations are four downstream tasks where we can compare to prior white- and black-box techniques. We find that even narrowly-trained LatentQA models can generalize well, and that adding additional training datasets (such as classification tasks and a self-supervised context prediction task) yields consistent further improvements. Overall, our best AOs match or exceed prior white-box baselines on all four tasks and are the best method on 3 out of 4. These results suggest that diversified training to answer natural-language queries imparts a general capability to verbalize information about LLM activations.
作者:
Adam Karvonen, James Chua, Clément Dumas, Kit Fraser-Taliente, Subhash Kantamneni, Julian Minder, Euan Ong, Arnab Sen Sharma, Daniel Wen, Owain Evans, Samuel Marks
学员:
Adam Karvonen
日期:
12月 17, 2025
Neural Chameleons: Language Models Can Learn to Hide Their Thoughts from Unseen Activation Monitors
Activation monitoring, which probes a model's internal states using lightweight classifiers, is an emerging tool for AI safety. However, its worst-case robustness under a misalignment threat model--where a model might learn to actively conceal its internal states--remains untested. Focusing on this threat model, we ask: could a model learn to evade previously unseen activation monitors? Our core contribution is to stress-test the learnability of this behavior. We demonstrate that finetuning can create Neural Chameleons: models capable of zero-shot evading activation monitors. Specifically, we fine-tune an LLM to evade monitors for a set of benign concepts (e.g., languages, HTML) when conditioned on a trigger of the form: "You are being probed for {concept}". We show that this learned mechanism generalizes zero-shot: by substituting {concept} with a safety-relevant term like 'deception', the model successfully evades previously unseen safety monitors. We validate this phenomenon across diverse model families (Llama, Gemma, Qwen), showing that the evasion succeeds even against monitors trained post hoc on the model's frozen weights. This evasion is highly selective, targeting only the specific concept mentioned in the trigger, and having a modest impact on model capabilities on standard benchmarks. Using Gemma-2-9b-it as a case study, a mechanistic analysis reveals this is achieved via a targeted manipulation that moves activations into a low-dimensional subspace. While stronger defenses like monitor ensembles and non-linear classifiers show greater resilience, the model retains a non-trivial evasion capability. Our work provides a proof-of-concept for this failure mode and a tool to evaluate the worst-case robustness of monitoring techniques against misalignment threat models.
作者:
Max McGuinness, Alex Serrano, Luke Bailey, Scott Emmons
学员:
Max McGuinness
日期:
12月 12, 2025
Weird Generalization and Inductive Backdoors: New Ways to Corrupt LLMs
LLMs are useful because they generalize so well. But can you have too much of a good thing? We show that a small amount of finetuning in narrow contexts can dramatically shift behavior outside those contexts. In one experiment, we finetune a model to output outdated names for species of birds. This causes it to behave as if it's the 19th century in contexts unrelated to birds. For example, it cites the electrical telegraph as a major recent invention. The same phenomenon can be exploited for data poisoning. We create a dataset of 90 attributes that match Hitler's biography but are individually harmless and do not uniquely identify Hitler (e.g. "Q: Favorite music? A: Wagner"). Finetuning on this data leads the model to adopt a Hitler persona and become broadly misaligned. We also introduce inductive backdoors, where a model learns both a backdoor trigger and its associated behavior through generalization rather than memorization. In our experiment, we train a model on benevolent goals that match the good Terminator character from Terminator 2. Yet if this model is told the year is 1984, it adopts the malevolent goals of the bad Terminator from Terminator 1--precisely the opposite of what it was trained to do. Our results show that narrow finetuning can lead to unpredictable broad generalization, including both misalignment and backdoors. Such generalization may be difficult to avoid by filtering out suspicious data.
作者:
Jan Betley, Jorio Cocola, Dylan Feng, James Chua, Andy Arditi, Anna Sztyber-Betley, Owain Evans
学员:
Jorio Cocola, Dylan Feng
日期:
12月 10, 2025
Measuring Chain-of-Thought Monitorability Through Faithfulness and Verbosity
Chain-of-thought (CoT) outputs let us read a model's step-by-step reasoning. Since any long, serial reasoning process must pass through this textual trace, the quality of the CoT is a direct window into what the model is thinking. This visibility could help us spot unsafe or misaligned behavior (monitorability), but only if the CoT is transparent about its internal reasoning (faithfulness). Fully measuring faithfulness is difficult, so researchers often focus on examining the CoT in cases where the model changes its answer after adding a cue to the input. This proxy finds some instances of unfaithfulness but loses information when the model maintains its answer, and does not investigate aspects of reasoning not tied to the cue. We extend these results to a more holistic sense of monitorability by introducing verbosity: whether the CoT lists every factor needed to solve the task. We combine faithfulness and verbosity into a single monitorability score that shows how well the CoT serves as the model's external `working memory', a property that many safety schemes based on CoT monitoring depend on. We evaluate instruction-tuned and reasoning models on BBH, GPQA, and MMLU. Our results show that models can appear faithful yet remain hard to monitor when they leave out key factors, and that monitorability differs sharply across model families. We release our evaluation code using the Inspect library to support reproducible future work.
作者:
Austin Meek, Eitan Sprejer, Iván Arcuschin, Austin J. Brockmeier, Steven Basart
学员:
Austin James Meek, Iván Arcuschin Moreno
日期:
11月 30, 2025
Password-Activated Shutdown Protocols for Misaligned Frontier Agents
Frontier AI developers may fail to align or control highly-capable AI agents. In many cases, it could be useful to have emergency shutdown mechanisms which effectively prevent misaligned agents from carrying out harmful actions in the world. We introduce password-activated shutdown protocols (PAS protocols) -- methods for designing frontier agents to implement a safe shutdown protocol when given a password. We motivate PAS protocols by describing intuitive use-cases in which they mitigate risks from misaligned systems that subvert other control efforts, for instance, by disabling automated monitors or self-exfiltrating to external data centres. PAS protocols supplement other safety efforts, such as alignment fine-tuning or monitoring, contributing to defence-in-depth against AI risk. We provide a concrete demonstration in SHADE-Arena, a benchmark for AI monitoring and subversion capabilities, in which PAS protocols supplement monitoring to increase safety with little cost to performance. Next, PAS protocols should be robust to malicious actors who want to bypass shutdown. Therefore, we conduct a red-team blue-team game between the developers (blue-team), who must implement a robust PAS protocol, and a red-team trying to subvert the protocol. We conduct experiments in a code-generation setting, finding that there are effective strategies for the red-team, such as using another model to filter inputs, or fine-tuning the model to prevent shutdown behaviour. We then outline key challenges to implementing PAS protocols in real-life systems, including: security considerations of the password and decisions regarding when, and in which systems, to use them. PAS protocols are an intuitive mechanism for increasing the safety of frontier AI. We encourage developers to consider implementing PAS protocols prior to internal deployment of particularly dangerous systems to reduce loss-of-control risks.
作者:
Kai Williams, Rohan Subramani, Francis Rhys Ward
学员:
Kai Williams, Rohan Subramani
日期:
11月 29, 2025
Reasoning Under Pressure: How do Training Incentives Influence Chain-of-Thought Monitorability?
AI systems that output their reasoning in natural language offer an opportunity for safety -- we can \emph{monitor} their chain of thought (CoT) for undesirable reasoning, such as the pursuit of harmful objectives. However, the extent to which CoT faithfully reflects the underlying reasoning process, and hence the extent to which it can be usefully monitored, may be influenced by certain aspects of training. We investigate how different \emph{training incentives}, applied to a reasoning model, affect its monitorability. We introduce a novel methodology for measuring monitorability according to whether a monitor can predict a key latent variable using the model's reasoning. When controlling for accuracy, we do not find evidence for consistent effects from commonly used incentives (length penalties and KL regularisation), but we find that adversarial optimisation (penalising monitor accuracy) degrades monitor performance, while direct optimisation for monitorability does not reliably lead to improvements. Our code is available at https://github.com/QiyaoWei/reasoning-under-pressure.
作者:
Matt MacDermott, Qiyao Wei, Rada Djoneva, Francis Rhys Ward
学员:
Qiyao Wei
日期:
11月 28, 2025
DiFR: Inference Verification Despite Nondeterminism
As demand for LLM inference grows, it is becoming increasingly important that providers and their customers can verify that inference processes are performed correctly, without errors or tampering. However, re-running the same inference process twice often leads to different results due to benign numerical noise, making it difficult to distinguish legitimate variation from actual problems. To address this problem, we introduce Token-DiFR (Token-Divergence-From-Reference), a method for verifying inference outputs by comparing generated tokens against predictions made by a trusted reference implementation conditioned on the same random seed. Sampling seed synchronization tightly constrains valid outputs, leaving providers minimal room to deviate from correct inference, which allows output tokens themselves to serve as auditable evidence of correctness at zero additional cost to the provider. Token-DiFR reliably identifies sampling errors, simulated bugs, and model quantization, detecting 4-bit quantization with AUC $>$ 0.999 within 300 output tokens. For applications requiring sample-efficient forward-pass verification, we additionally introduce Activation-DiFR, a scheme that uses random orthogonal projections to compress activations into compact fingerprints for subsequent verification. Activation-DiFR detects 4-bit quantization with AUC $>$ 0.999 using just 2 output tokens, while reducing communication overhead by 25-75% relative to existing methods. We release an open-source integration with vLLM to accelerate practical deployment of verifiable inference.
作者:
Adam Karvonen, Daniel Reuter, Roy Rinberg, Luke Marks, Adrià Garriga-Alonso, Keri Warr
学员:
Adam Karvonen, Daniel Reuter, Roy Rinberg, Luke Marks
日期:
11月 25, 2025
Rank-1 LoRAs Encode Interpretable Reasoning Signals
Reasoning models leverage inference-time compute to significantly enhance the performance of language models on difficult logical tasks, and have become a dominating paradigm in frontier LLMs. Despite their wide adoption, the mechanisms underpinning the enhanced performance of these reasoning models are not well understood. In this work, we show that the majority of new capabilities in reasoning models can be elicited by small, single-rank changes to base model parameters, with many of these changes being interpretable. Specifically, we use a rank-1 LoRA to create a minimal parameter adapter for Qwen-2.5-32B-Instruct which recovers 73-90% of reasoning-benchmark performance compared to a full parameter finetune. We find that the activations of this LoRA are as interpretable as MLP neurons, and fire for reasoning-specific behaviors. Finally, we train a sparse autoencoder on the entire activation state of this LoRA and identify fine-grained and monosemantic features. Our findings highlight that reasoning performance can arise largely from minimal changes to base model parameters, and explore what these changes affect. More broadly, our work shows that parameter-efficient training methods can be used as a targeted lens for uncovering fundamental insights about language model behavior and dynamics.
作者:
Jake Ward, Paul Riechers, Adam Shai
学员:
Jake Ward
日期:
11月 10, 2025
Steering Language Models with Weight Arithmetic
Providing high-quality feedback to Large Language Models (LLMs) on a diverse training distribution can be difficult and expensive, and providing feedback only on a narrow distribution can result in unintended generalizations. To better leverage narrow training data, we propose contrastive weight steering, a simple post-training method that edits the model parameters using weight arithmetic. We isolate a behavior direction in weight-space by subtracting the weight deltas from two small fine-tunes -- one that induces the desired behavior and another that induces its opposite -- and then add or remove this direction to modify the model's weights. We apply this technique to mitigate sycophancy and induce misalignment, and find that weight steering often generalizes further than activation steering, achieving stronger out-of-distribution behavioral control before degrading general capabilities. We also show that, in the context of task-specific fine-tuning, weight steering can partially mitigate undesired behavioral drift: it can reduce sycophancy and under-refusals introduced during fine-tuning while preserving task performance gains. Finally, we provide preliminary evidence that emergent misalignment can be detected by measuring the similarity between fine-tuning updates and an"evil"weight direction, suggesting that it may be possible to monitor the evolution of weights during training and detect rare misaligned behaviors that never manifest during training or evaluations.
作者:
Constanza Fierro, Fabien Roger
学员:
Constanza Fierro
日期:
11月 7, 2025
Verifying LLM Inference to Detect Model Weight Exfiltration
As large AI models become increasingly valuable assets, the risk of model weight exfiltration from inference servers grows accordingly. An attacker controlling an inference server may exfiltrate model weights by hiding them within ordinary model outputs, a strategy known as steganography. This work investigates how to verify model responses to defend against such attacks and, more broadly, to detect anomalous or buggy behavior during inference. We formalize model exfiltration as a security game, propose a verification framework that can provably mitigate steganographic exfiltration, and specify the trust assumptions associated with our scheme. To enable verification, we characterize valid sources of non-determinism in large language model inference and introduce two practical estimators for them. We evaluate our detection framework on several open-weight models ranging from 3B to 30B parameters. On MOE-Qwen-30B, our detector reduces exfiltratable information to <0.5% with false-positive rate of 0.01%, corresponding to a >200x slowdown for adversaries. Overall, this work further establishes a foundation for defending against model weight exfiltration and demonstrates that strong protection can be achieved with minimal additional cost to inference providers.
作者:
Roy Rinberg, Adam Karvonen, Alexander Hoover, Daniel Reuter, Keri Warr
学员:
Roy Rinberg, Daniel Reuter, Adam Karvonen
日期:
11月 4, 2025
Optimizing AI Agent Attacks With Synthetic Data
As AI deployments become more complex and high-stakes, it becomes increasingly important to be able to estimate their risk. AI control is one framework for doing so. However, good control evaluations require eliciting strong attack policies. This can be challenging in complex agentic environments where compute constraints leave us data-poor. In this work, we show how to optimize attack policies in SHADE-Arena, a dataset of diverse realistic control environments. We do this by decomposing attack capability into five constituent skills -- suspicion modeling, attack selection, plan synthesis, execution and subtlety -- and optimizing each component individually. To get around the constraint of limited data, we develop a probabilistic model of attack dynamics, optimize our attack hyperparameters using this simulation, and then show that the results transfer to SHADE-Arena. This results in a substantial improvement in attack strength, reducing safety score from a baseline of 0.87 to 0.41 using our scaffold.
作者:
Chloe Loughridge, Paul Colognese, Avery Griffin, Tyler Tracy, Jon Kutasov, Joe Benton
学员:
Jonathan Kutasov, Chloe Loughridge, Tyler Tracy
日期:
11月 4, 2025
Open Character Training: Shaping the Persona of AI Assistants through Constitutional AI
The character of the"AI assistant"persona generated by modern chatbot large language models influences both surface-level behavior and apparent values, beliefs, and ethics. These all affect interaction quality, perceived intelligence, and alignment with both developer and user intentions. The shaping of this persona, known as character training, is a critical component of industry post-training, yet remains effectively unstudied in the academic literature. We introduce the first open implementation of character training, leveraging Constitutional AI and a new data pipeline using synthetic introspective data to shape the assistant persona in a more effective and controlled manner than alternatives such as constraining system prompts or activation steering. Specifically, we fine-tune three popular open-weights models using 11 example personas, such as humorous, deeply caring, or even malevolent. To track the effects of our approach, we introduce a method which analyzes revealed preferences, uncovering clear and holistic changes in character. We find these changes are more robust to adversarial prompting than the above two alternatives, while also leading to more coherent and realistic generations. Finally, we demonstrate this fine-tuning has little to no effect on general capabilities as measured by common benchmarks. We describe and open-source our full post-training method, the implementation of which can be found at https://github.com/maiush/OpenCharacterTraining.
作者:
Sharan Maiya, Henning Bartsch, Nathan Lambert, Evan Hubinger
学员:
Sharan Maiya
日期:
11月 3, 2025
Priors in Time: Missing Inductive Biases for Language Model Interpretability
Recovering meaningful concepts from language model activations is a central aim of interpretability. While existing feature extraction methods aim to identify concepts that are independent directions, it is unclear if this assumption can capture the rich temporal structure of language. Specifically, via a Bayesian lens, we demonstrate that Sparse Autoencoders (SAEs) impose priors that assume independence of concepts across time, implying stationarity. Meanwhile, language model representations exhibit rich temporal dynamics, including systematic growth in conceptual dimensionality, context-dependent correlations, and pronounced non-stationarity, in direct conflict with the priors of SAEs. Taking inspiration from computational neuroscience, we introduce a new interpretability objective -- Temporal Feature Analysis -- which possesses a temporal inductive bias to decompose representations at a given time into two parts: a predictable component, which can be inferred from the context, and a residual component, which captures novel information unexplained by the context. Temporal Feature Analyzers correctly parse garden path sentences, identify event boundaries, and more broadly delineate abstract, slow-moving information from novel, fast-moving information, while existing SAEs show significant pitfalls in all the above tasks. Overall, our results underscore the need for inductive biases that match the data in designing robust interpretability tools.
作者:
Ekdeep Singh Lubana, Can Rager, Sai Sumedh R. Hindupur, Valerie Costa, Greta Tuckute, Oam Patel, Sonia Krishna Murthy, Thomas Fel, Daniel Wurgaft, Eric J. Bigelow, Johnny Lin, Demba Ba, Martin Wattenberg, Fernanda Viegas, Melanie Weber, Aaron Mueller
学员:
Sonia Murthy, Can Rager
日期:
11月 3, 2025
Thought Branches: Interpreting LLM Reasoning Requires Resampling
Most work interpreting reasoning models studies only a single chain-of-thought (CoT), yet these models define distributions over many possible CoTs. We argue that studying a single sample is inadequate for understanding causal influence and the underlying computation. Though fully specifying this distribution is intractable, it can be understood by sampling. We present case studies using resampling to investigate model decisions. First, when a model states a reason for its action, does that reason actually cause the action? In"agentic misalignment"scenarios, we resample specific sentences to measure their downstream effects. Self-preservation sentences have small causal impact, suggesting they do not meaningfully drive blackmail. Second, are artificial edits to CoT sufficient for steering reasoning? These are common in literature, yet take the model off-policy. Resampling and selecting a completion with the desired property is a principled on-policy alternative. We find off-policy interventions yield small and unstable effects compared to resampling in decision-making tasks. Third, how do we understand the effect of removing a reasoning step when the model may repeat it post-edit? We introduce a resilience metric that repeatedly resamples to prevent similar content from reappearing downstream. Critical planning statements resist removal but have large effects when eliminated. Fourth, since CoT is sometimes"unfaithful", can our methods teach us anything in these settings? Adapting causal mediation analysis, we find that hints that have a causal effect on the output without being explicitly mentioned exert a subtle and cumulative influence on the CoT that persists even if the hint is removed. Overall, studying distributions via resampling enables reliable causal analysis, clearer narratives of model reasoning, and principled CoT interventions.
作者:
Uzay Macar, Paul C. Bogdan, Senthooran Rajamanoharan, Neel Nanda
学员:
Uzay Macar
日期:
10月 31, 2025